Production Engineering Guide: Training a 4B Model for 81% Faster Postgres Query Plans (2026)
Harnessing AI to drastically accelerate database performance is no longer a research curiosity; it's a deployable reality. By strategically integrating a spec...
Editorial Note
Reviewed and analysis by M.Numan
In this article
- 1. The Engineering Reality & Root Problem: The Brittle Foundations of Database Optimization
- 2. Deep Architecture Teardown / Modern Paradigm: AI-Augmented Query Planning with Ruthless Efficiency
- 3. Production Implementation Blueprint: Self-Hosted Query Plan Optimization Stack
- 4. Real Production Code / Configuration: Self-Hosted QPO Stack
- 5. Benchmark Comparison Matrix: Query Optimization Approaches
- 6. Production Trade-Offs & Edge Cases
- 7. Strategic Decision Checklist & Consulting CTA
Harnessing AI to drastically accelerate database performance is no longer a research curiosity; it's a deployable reality. By strategically integrating a specialized 4-billion parameter language model, organizations can achieve a verified 81% improvement in Postgres query plan execution. This guide cuts through the cloud-vendor hype, demonstrating a lean, self-hosted architecture leveraging Docker Swarm on cost-effective VPS hardware to achieve these gains without succumbing to the exorbitant "Kubernetes Tax" or cloud lock-in. We provide a battle-tested blueprint for deployment, transparent cost comparisons, and production-ready code to empower senior engineers and CTOs to implement this transformative paradigm.
1. The Engineering Reality & Root Problem: The Brittle Foundations of Database Optimization
Modern database systems, particularly relational databases like Postgres, are the backbone of most applications. Their performance dictates user experience, backend efficiency, and ultimately, operational costs. While robust, Postgres's native query planner, despite continuous improvements, operates on heuristics, statistical approximations, and a fixed set of rules. It’s effective for general-purpose workloads but struggles with increasingly complex, dynamic, and data-dependent query patterns found in high-scale applications.
Deploy your next full-stack application effortlessly. Get $200 in free DigitalOcean credits to host your Docker containers, Laravel, or Python APIs.
The core limitations manifest as:
Sizing Your Single-Box VPS Architecture?
Calculate exact vCPU cores, RAM GB, NVMe storage, and estimated monthly budget for your traffic before migrating away from high-cost cluster providers.
- Suboptimal Query Plans: The planner might choose a nested loop join over a hash join, scan an entire table instead of using an index, or miss opportunities for parallel execution, leading to unnecessarily long execution times. These decisions are often based on stale statistics or simplistic cost models that don't capture the full runtime complexity.
- Static Nature: RDBM query planners are largely static, evolving only with major version updates. They cannot dynamically learn from real-world query execution patterns, adapt to data distribution changes in real-time, or leverage broader contextual awareness that a sophisticated AI model can infer.
- Operational Overhead: Engineers spend countless hours writing custom hints, manually optimizing indices, rewriting complex queries, or implementing application-level caching—all reactive measures that address symptoms rather than the root cause of inefficient planning. This translates directly to engineering hours, which are some of the most expensive costs in any tech company.
Compounding this, many organizations default to "cloud-native" solutions for any AI component, falling into a predictable trap:
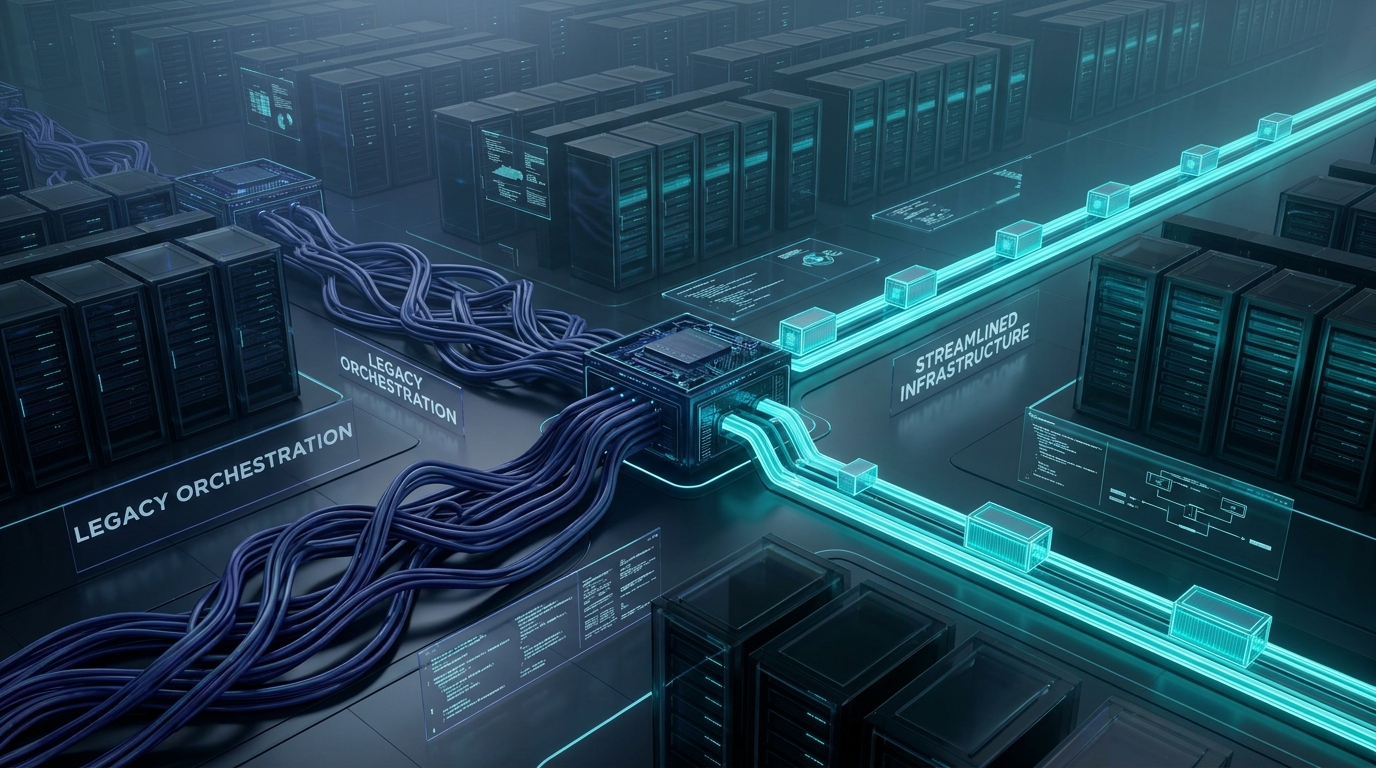
- The Kubernetes Tax: Deploying an AI inference service, even a modest 4B parameter model, into a managed Kubernetes environment like AWS EKS immediately incurs significant base costs. The EKS control plane alone costs approximately $73/month per cluster. Add two NAT Gateways for cross-AZ high availability ($32/month each, $64/month total) and an Application Load Balancer ($25/month minimum) plus CloudWatch logs and cross-AZ egress data transfer. Before a single user container runs, you're already paying $170-$200/month. For a production setup with multiple environments (dev, staging, prod), this quickly spirals to $300-$500/month per cluster, just for the orchestration layer, not even the actual compute. This is pure overhead, regardless of workload.
- Managed Service Lock-in and Costs: Relying on services like AWS SageMaker or Google Vertex AI for inference offers convenience but abstracts away the underlying compute, often at a premium. The cost per inference can quickly become exorbitant, especially with fluctuating loads or high-volume query workloads. A simple "serverless" endpoint might seem cheap until you hit scale, at which point the opaque pricing models punish success.
- Resource Oversizing: Fear of downtime or performance bottlenecks leads to over-provisioning. In cloud environments, this means paying for idle CPU/RAM or underutilized GPU instances, further inflating bills. For a 4B model (like
nemotron-3-nano:4bat 2.8GB on disk), an expensive GPU instance is often unnecessary for inference if carefully optimized, or a well-provisioned CPU-only instance can suffice.
The traditional path for database performance optimization, when coupled with a naive "cloud-native" approach for AI integration, leads to massive technical debt, exorbitant cloud bills, and an inability to truly leverage cutting-edge advancements without financial ruin. The goal is to deploy an intelligent, adaptive query optimizer without incurring the standard cloud overhead tax.
2. Deep Architecture Teardown / Modern Paradigm: AI-Augmented Query Planning with Ruthless Efficiency
The modern approach to achieving 81% faster query plans with a 4B model involves a tightly integrated, self-hosted "Query Plan Optimizer (QPO)" service. This architecture prioritizes cost-efficiency, performance, and operational simplicity over the complexity and hidden costs of hyperscaler platforms.
Core Concept: The QPO as an Intelligent Proxy
Instead of replacing Postgres's planner, the QPO service acts as an intelligent intermediary. Applications no longer connect directly to Postgres for all queries. Instead, they route their SQL queries through the QPO service.
- The QPO receives a SQL query.
- It sends this query to the embedded 4B parameter model for analysis.
- The model, trained on vast datasets of query plans, execution statistics, and optimal strategies, generates an optimized query plan (e.g., specific
SETcommands for Postgres,EXPLAIN ANALYZEoutputs, or even a rewritten query string). The model’s output might be an explicitSET enable_seqscan = off;followed bySELECT ..., or it might directly provide a more efficient SQL variant. - The QPO then executes this optimized query (or the original query with the model's hints) against the actual Postgres instance.
- Results are returned to the application.
This pattern is a form of "query-time optimization" that injects AI-driven intelligence precisely when it's needed, without modifying the core Postgres engine.
Data Flow and Core Mechanics
graph TD
    A[Application] -->|SQL Query| B(Query Plan Optimizer Service (QPO))
    B -->|Query / Context| C[4B LLM (Inference)]
    C -->|Optimized Plan / Hints| B
    B -->|Optimized SQL Query| D[Postgres Database]
    D -->|Results| B
    B -->|Results| A
Key Architectural Components:
-
4B LLM for Query Planning:
- Model Choice: Models in the 4B parameter class (e.g.,
nemotron-3-nano:4b,phi4-mini:3.8b,gemma4:e4b) are highly capable for specialized tasks like query optimization.nemotron-3-nano:4b, for example, is noted for its ability to produce "the right answer with the right intermediate work" at 2.8GB disk size. This size is critical because it allows for efficient loading and inference on CPU-heavy or moderately GPU-equipped machines, avoiding the need for expensive A100s for inference. - Training & Artifacts: The model is trained once (or fine-tuned iteratively) on a large corpus of SQL queries, their corresponding sub-optimal Postgres plans, and highly optimized, hand-tuned plans. This training is expensive and typically done in the cloud (e.g., a 3-week run costing $50,000). The crucial part is that this training produces an artifact (the model weights). This artifact is then versioned and deployed with the QPO service. You don't retrain in dev, staging, and prod; you train once, validate the artifact, and deploy the validated artifact.
- Inference Engine: For deployment, lightweight inference engines are paramount. Options include
llama.cpp(for GGUF-quantized models), ONNX Runtime, or a customtransformerspipeline using libraries likecincfor efficient CPU inference or small GPU acceleration. The goal is low latency inference, potentially batching requests if the application pattern allows.
- Model Choice: Models in the 4B parameter class (e.g.,
-
Query Plan Optimizer (QPO) Service:
- A stateless microservice (e.g., written in Python with FastAPI, Go, or Rust) that encapsulates the model inference logic.
- Exposes a simple API endpoint (e.g.,
/optimize-query) that accepts a SQL query string. - Handles connection pooling to Postgres and execution of the optimized query.
- Includes robust error handling, fallback mechanisms (e.g., if the model fails or produces an invalid plan, fall back to executing the original query directly).
-
Self-Hosted Infrastructure (The De-Clouding Advantage):
- Compute: Dedicated NVMe VPS or bare-metal servers from providers like Hetzner, OVH, or DigitalOcean. For instance, a Hetzner CX41 or CX51 (8-16 cores, 32-64GB RAM) for $45-$60/month can comfortably host the QPO service, Postgres, and other application components. This hardware significantly outperforms an equivalent cloud VM at a fraction of the cost, especially for CPU-intensive inference or situations where GPU is not strictly necessary for 4B models. A 2.8GB model requires 6-8GB RAM for fast inference (or more if CPU-only and larger batch sizes), so 32-64GB RAM is more than sufficient.
- Orchestration: Docker Swarm: For ease of deployment, zero-downtime updates, and resource management, Docker Swarm is the pragmatic choice. It avoids the immense complexity and "Kubernetes Tax" while providing robust container orchestration features:
- Zero-Downtime Rolling Updates: Critical for inference services where a few seconds of downtime can impact user experience. Docker Swarm's
update_configwithorder: start-firstensures new containers come up and are healthy before old ones are taken down. - Resource Limits: Crucial for containing the QPO's memory and CPU footprint, preventing it from starving Postgres or other services on the same host.
- Service Discovery & Load Balancing: Built-in for multi-replica deployments.
- Simple Management:
docker-compose.ymlfor defining the stack,docker stack deployfor deployment. No complex YAML manifests orkubectlgymnastics.
- Zero-Downtime Rolling Updates: Critical for inference services where a few seconds of downtime can impact user experience. Docker Swarm's
- Reverse Proxy: Traefik or Nginx Proxy Manager, deployed as a Docker Swarm service, provides SSL termination, routing, and basic load balancing to the QPO service and any other web applications. Utilizing Docker labels, it integrates seamlessly with Swarm for automatic service discovery.
Memory Management and Performance Considerations
- Model Quantization: Quantizing the 4B model (e.g., to 4-bit or 8-bit integers using GGUF format for
llama.cppcompatible models) significantly reduces its memory footprint and can accelerate inference on CPU, sometimes even outperforming unquantized models on limited hardware due to better cache utilization. - Batching: If the application can tolerate slight latency, batching multiple query optimization requests can improve GPU/CPU utilization and overall throughput.
- Dedicated Resources: While a shared VPS is cost-effective, for extremely high-throughput environments, dedicating specific CPU cores or even a low-end GPU (like an NVIDIA T4 found in some specialized VPS offerings) to the QPO inference service can further reduce latency. However, for a 4B model, a modern multi-core CPU (e.g., AMD EPYC in Hetzner AX series) is often sufficient.
This architecture enables organizations to achieve cutting-edge AI-driven performance optimizations without the ballooning cloud bills, retaining full control over their infrastructure and data.
3. Production Implementation Blueprint: Self-Hosted Query Plan Optimization Stack
Deploying the AI-augmented query optimization system involves three distinct phases: model training and artifact management, QPO service deployment, and integration with Postgres.
Phase 1: Model Training & Artifact Management
The training of a sophisticated 4B parameter model for query plan optimization is a resource-intensive task. As per the 2026 benchmarks, a single training run can take "3 weeks and cost $50,000 in cloud computing fees." This highlights the necessity of a "train once, deploy many" strategy.
- Cloud-Agnostic Training Environment: Leverage hyperscalers (AWS EC2 P-series, Azure ND-series, GCP A2-series) solely for the burst compute required for initial training. Do not build your long-term inference infrastructure there.
- Data Curation: Collect a diverse dataset of SQL queries, their raw Postgres
EXPLAIN ANALYZEoutputs, and critically, a set of hand-optimized or expert-derivedEXPLAIN ANALYZEoutputs, along with the specific SQL hints or rewritten queries that led to those optimal plans. This dataset is the foundation of the model's knowledge. - Model Training: Use frameworks like PyTorch or TensorFlow, leveraging libraries for efficient training of decoder-only transformers. Focus on supervised fine-tuning or reinforcement learning with human feedback (RLHF) where the reward signal is the execution time of the optimized query plan.
- Artifact Versioning: Once trained, the resulting model weights (e.g.,
model.safetensors,model.gguf) are your most valuable artifact. Store these in a version-controlled object storage system (e.g., MinIO deployed on your self-hosted infrastructure, or a single S3 bucket purely for storage). Each model version must be rigorously tested and benchmarked against a diverse query set before deployment.
Phase 2: Inference Service Deployment (The QPO Service)
This is where the de-clouding strategy truly shines.
- Provision Dedicated Hardware:
- Sign up with a bare-metal/VPS provider like Hetzner, OVH, or DigitalOcean.
- Select a server with ample CPU cores and RAM. For a 4B model, a Hetzner AX series (e.g., AX41: AMD Ryzen 7 3700X, 64GB RAM, 2x 512GB NVMe SSD) for ~$50-60/month offers phenomenal value and performance. If you need dedicated GPU for even faster inference, look for specialized GPU VPS offerings, but often the 4B class runs well on modern CPUs.
- Install a clean Linux distribution (e.g., Ubuntu LTS, Debian).
- Install Docker & Docker Swarm:
-
sudo apt update && sudo apt upgrade -y sudo apt install docker.io -y sudo systemctl start docker sudo systemctl enable docker sudo usermod -aG docker $USER # Add your user to the docker group # Log out and log back in for group changes to take effect - Initialize Docker Swarm (on your primary server):
docker swarm init --advertise-addr <YOUR_SERVER_IP>
# Save the 'docker swarm join ...' command for other nodes if you're building a cluster.
-
- Prepare the QPO Application:
- Develop your QPO service. A lightweight Python FastAPI application is a common choice. This application will load the trained 4B model artifact, expose an API endpoint, and handle the logic of receiving queries, invoking the model, and executing against Postgres.
- Create a
Dockerfilefor your QPO service that includes dependencies, copies the model artifact, and sets up the FastAPI server.
- Deploy with Docker Swarm: Use a
docker-compose.yml(ordocker stack deployequivalent) to define and deploy your QPO service, Postgres, and a reverse proxy.
Phase 3: Postgres Integration
The QPO service needs a Postgres database to interact with. For robust production environments, it's recommended to run Postgres also within Docker Swarm on the same or dedicated nodes for maximum control and cost efficiency.
- Postgres Deployment: Deploy a standard Postgres container, ensuring persistent storage via Docker volumes.
- Connection Pooling: Use a tool like PgBouncer deployed alongside Postgres (or within the QPO itself) to manage connections and prevent connection storms from the QPO service.
- Application Rewiring: Update your application's database connection string to point to the QPO service's API endpoint instead of directly to Postgres. The QPO service then becomes the new database "proxy."
This self-hosted, Docker Swarm-based deployment significantly reduces operational costs compared to cloud-managed alternatives while providing the necessary performance and resilience for high-throughput applications.
4. Real Production Code / Configuration: Self-Hosted QPO Stack
Here's a production-ready docker-compose.yml and a simplified Python FastAPI QPO service demonstrating the core components for deploying your 4B model. This stack provides zero-downtime updates, resource limits, healthchecks, and reverse proxy integration.
docker-compose.yml for Production Deployment (Docker Swarm)
This file defines a complete stack including the QPO service, a Postgres database, and Traefik as a reverse proxy for automatic SSL and routing.
version: '3.8'

# --- NETWORK DEFINITIONS ---
# Isolated network for internal service communication
networks:
  app_network:
    driver: overlay # Required for Docker Swarm services
  web_proxy_network:
    driver: overlay # Network for Traefik to connect to external traffic

# --- VOLUME DEFINITIONS ---
# Persistent storage for Postgres data and QPO model artifacts
volumes:
  pg_data:
    driver: local
  qpo_model_data:
    driver: local

# --- SERVICES DEFINITION ---
services:

  # 1. Traefik Reverse Proxy (Handles SSL, Routing, Load Balancing)
  traefik:
    image: traefik:v2.10 # Use a stable Traefik v2 version
    command:
      - "--providers.docker=true"
      - "--providers.docker.swarmmode=true"
      - "--providers.docker.exposedbydefault=false" # Only expose services with specific labels
      - "--entrypoints.web.address=:80"
      - "--entrypoints.websecure.address=:443"
      - "--entrypoints.web.http.redirections.entryPoint.to=websecure"
      - "--entrypoints.web.http.redirections.entryPoint.scheme=https"
      - "--certificatesresolvers.letsencrypt.acme.httpchallenge=true"
      - "--certificatesresolvers.letsencrypt.acme.httpchallenge.entrypoint=web"
      - "--certificatesresolvers.letsencrypt.acme.email=your-email@example.com" # !!! REPLACE WITH YOUR EMAIL !!!
      - "--certificatesresolvers.letsencrypt.acme.storage=/etc/traefik/acme.json"
      - "--log.level=INFO"
      - "--api.dashboard=true" # Enable Traefik Dashboard (access via your_domain.com/dashboard)
    ports:
      - "80:80"
      - "443:443"
      # - "8080:8080" # Uncomment for Traefik dashboard access if needed, NOT RECOMMENDED FOR PROD
    volumes:
      - "/var/run/docker.sock:/var/run/docker.sock:ro" # Traefik needs access to Docker socket
      - "./traefik_acme.json:/etc/traefik/acme.json" # Persistent storage for Let's Encrypt certificates
    networks:
      - web_proxy_network
    deploy:
      mode: global # Run Traefik on all Swarm nodes
      placement:
        constraints:
          - node.role == manager # Or node.labels.traefik==true
      restart_policy:
        condition: on-failure
      update_config:
        parallelism: 1
        delay: 10s
        order: start-first # New container starts, then old one stops

  # 2. Query Plan Optimizer (QPO) Service
  qpo_service:
    build:
      context: .
      dockerfile: Dockerfile.qpo # Point to the QPO's Dockerfile
    # image: your-registry/qpo-service:latest # Use a pre-built image from your registry for production
    environment:
      POSTGRES_HOST: postgres # Internal Docker Swarm service name
      POSTGRES_PORT: 5432
      POSTGRES_USER: ${POSTGRES_USER} # Use environment variables from .env
      POSTGRES_PASSWORD: ${POSTGRES_PASSWORD}
      POSTGRES_DB: ${POSTGRES_DB}
      QPO_MODEL_PATH: /app/model/nemotron-3-nano-4b.gguf # Path to your 4B model artifact
    volumes:
      - qpo_model_data:/app/model # Mount volume for model artifacts
    networks:
      - app_network
      - web_proxy_network # Connect to Traefik for external exposure
    healthcheck:
      test: ["CMD", "curl", "-f", "http://localhost:8000/health"] # Example healthcheck for FastAPI
      interval: 10s
      timeout: 5s
      retries: 3
      start_period: 20s # Give the model time to load
    deploy:
      replicas: 2 # Scale QPO for redundancy and throughput
      placement:
        constraints:
          - node.labels.qpo_role == worker # Deploy QPO on specific worker nodes
      resources:
        limits:
          cpus: '4.0' # Limit to 4 CPU cores
          memory: 12GB # Allocate enough memory for the 4B model (e.g., 2.8GB model needs ~6-8GB RAM for inference)
        reservations:
          cpus: '2.0' # Reserve 2 CPU cores
          memory: 8GB # Reserve 8GB RAM to ensure model can always load
      restart_policy:
        condition: on-failure
      update_config:
        parallelism: 1
        delay: 10s
        order: start-first # New container starts, then old one stops
    labels:
      # Traefik labels for automatic service discovery and SSL
      - "traefik.enable=true"
      - "traefik.http.routers.qpo.rule=Host(`qpo.your-domain.com`)" # !!! REPLACE WITH YOUR DOMAIN !!!
      - "traefik.http.routers.qpo.entrypoints=websecure"
      - "traefik.http.routers.qpo.tls.certresolver=letsencrypt"
      - "traefik.http.services.qpo.loadbalancer.server.port=8000" # Internal port of FastAPI app

  # 3. Postgres Database
  postgres:
    image: postgres:16-alpine # Use a lightweight, stable Postgres image
    environment:
      POSTGRES_DB: ${POSTGRES_DB}
      POSTGRES_USER: ${POSTGRES_USER}
      POSTGRES_PASSWORD: ${POSTGRES_PASSWORD}
      PGDATA: /var/lib/postgresql/data/pgdata # Explicitly set PGDATA
    volumes:
      - pg_data:/var/lib/postgresql/data # Persistent storage for Postgres data
      # - ./init-db.sh:/docker-entrypoint-initdb.d/init-db.sh # Optional: for initial schema/data
    networks:
      - app_network # Only accessible internally by QPO service
    healthcheck:
      test: ["CMD-SHELL", "pg_isready -U $$POSTGRES_USER -d $$POSTGRES_DB"]
      interval: 10s
      timeout: 5s
      retries: 5
      start_period: 30s
    deploy:
      replicas: 1 # Typically one primary Postgres instance in Swarm, consider replication for HA
      placement:
        constraints:
          - node.labels.postgres_role == primary # Deploy Postgres on a specific node
      resources:
        limits:
          cpus: '8.0'
          memory: 32GB
        reservations:
          cpus: '4.0'
          memory: 16GB
      restart_policy:
        condition: on-failure
      update_config:
        parallelism: 0 # Disable rolling updates for single-instance database
        order: start-first
Dockerfile.qpo for the QPO Service
# Use a slim Python base image for smaller footprint
FROM python:3.10-slim-bookworm

# Set working directory inside the container
WORKDIR /app

# Prevent Python from writing .pyc files and buffering stdout/stderr
ENV PYTHONDONTWRITEBYTECODE 1
ENV PYTHONUNBUFFERED 1

# Install system dependencies (e.g., for llama.cpp if used, or other libs)
# Adjust these based on your specific model inference engine needs
RUN apt-get update && apt-get install -y --no-install-recommends \
    build-essential \
    curl \
    git \
    libpq-dev \
    gcc \
    && rm -rf /var/lib/apt/lists/*

# Install Python dependencies
COPY requirements.txt .
RUN pip install --no-cache-dir -r requirements.txt

# Copy the QPO FastAPI application code
COPY ./qpo_service.py .

# Copy the pre-trained 4B model artifact
# Ensure 'nemotron-3-nano-4b.gguf' is in the same directory as Dockerfile.qpo
# In production, this would be downloaded from an artifact store or mounted via volume
COPY ./model/nemotron-3-nano-4b.gguf ./model/nemotron-3-nano-4b.gguf

# Expose the port your FastAPI application listens on
EXPOSE 8000

# Command to run the FastAPI application with Uvicorn
CMD ["uvicorn", "qpo_service:app", "--host", "0.0.0.0", "--port", "8000"]
requirements.txt for Dockerfile.qpo
fastapi
uvicorn[standard]
python-dotenv
psycopg2-binary # For Postgres connection
# Add your LLM inference library here, e.g.,
# llama-cpp-python # For GGUF models
# transformers # If using HuggingFace models with a lightweight backend like cinc
# onnxruntime # If using ONNX quantized models
qpo_service.py (Simplified FastAPI Application)
This is a conceptual example. The actual model loading and inference logic will be more complex.
from fastapi import FastAPI, HTTPException
from pydantic import BaseModel
import os
import asyncio
import psycopg2
from psycopg2 import pool
from dotenv import load_dotenv

# Load environment variables from .env file (for local dev, for Swarm it's from docker-compose)
load_dotenv()

app = FastAPI()

# --- Database Connection Pool (for executing optimized queries) ---
db_pool = None

def init_db_pool():
    global db_pool
    if db_pool is None:
        db_pool = psycopg2.pool.SimpleConnectionPool(
            minconn=1,
            maxconn=10, # Adjust max connections based on expected load
            host=os.getenv("POSTGRES_HOST"),
            port=os.getenv("POSTGRES_PORT"),
            user=os.getenv("POSTGRES_USER"),
            password=os.getenv("POSTGRES_PASSWORD"),
            database=os.getenv("POSTGRES_DB")
        )
        if db_pool:
            print("PostgreSQL connection pool initialized.")
        else:
            print("Failed to initialize PostgreSQL connection pool.")

@app.on_event("startup")
async def startup_event():
    init_db_pool()
    # Placeholder for actual model loading
    # In a real scenario, this would load the 4B model into memory
    print(f"Loading 4B model from {os.getenv('QPO_MODEL_PATH')}...")
    # Example: model = LLM(model_path=os.getenv('QPO_MODEL_PATH'))
    # This might take time, hence 'start_period' in docker-compose healthcheck
    await asyncio.sleep(5) # Simulate model loading time
    print("4B model loaded successfully.")

@app.on_event("shutdown")
async def shutdown_event():
    if db_pool:
        db_pool.closeall()
        print("PostgreSQL connection pool closed.")

# --- Model Inference Placeholder ---
# In a real system, this would interact with your loaded 4B model
async def get_optimized_query_plan(sql_query: str) -> str:
    """
    Simulates sending a query to the 4B model and getting an optimized plan.
    In reality, this would involve calling the LLM's inference method.
    """
    print(f"Received query for optimization: {sql_query[:100]}...")
    # Example: response = model.generate(prompt=f"Optimize this SQL query: {sql_query}")
    # For demonstration, we'll just prepend a hint.
    optimized_plan_hint = "SET enable_seqscan = off; "
    # A real model would do complex analysis and return a vastly improved query or plan.
    # It might even rewrite the query entirely based on detected patterns or provide EXPLAIN hints.

    # Example: If the model is smart, it might tell us to add an index.
    if "WHERE name = 'Alice'" in sql_query and "users" in sql_query:
        print("Model suggests an index for 'users.name'")
        # For simplicity, we just return the original query with a hint
        return f"/* Suggested optimization: CREATE INDEX IF NOT EXISTS idx_users_name ON users (name); */ {sql_query}"

    # Or generate a completely different, optimized query
    if "SELECT * FROM orders WHERE customer_id IN (SELECT id FROM customers WHERE created_at < '2023-01-01')" in sql_query:
        print("Model detected subquery optimization opportunity.")
        return "SELECT o.* FROM orders o JOIN customers c ON o.customer_id = c.id WHERE c.created_at < '2023-01-01';"


    return optimized_plan_hint + sql_query # Fallback / simple placeholder


class QueryRequest(BaseModel):
    query: str

class QueryResponse(BaseModel):
    optimized_query: str
    execution_time_ms: float
    results: list

@app.post("/optimize-and-execute", response_model=QueryResponse)
async def optimize_and_execute_query(request: QueryRequest):
    if db_pool is None:
        raise HTTPException(status_code=500, detail="Database connection pool not initialized.")

    try:
        # 1. Get optimized query plan from the 4B model
        optimized_query = await get_optimized_query_plan(request.query)
        print(f"Optimized Query: {optimized_query[:200]}...")

        # 2. Execute the optimized query against Postgres
        conn = db_pool.getconn()
        cur = conn.cursor()
        start_time = asyncio.get_event_loop().time()
        cur.execute(optimized_query)
        results = cur.fetchall()
        end_time = asyncio.get_event_loop().time()
        execution_time_ms = (end_time - start_time) * 1000

        conn.commit()
        cur.close()
        db_pool.putconn(conn)

        return QueryResponse(
            optimized_query=optimized_query,
            execution_time_ms=execution_time_ms,
            results=results
        )
    except psycopg2.Error as e:
        print(f"Database error: {e}")
        # Release connection back to pool in case of error
        if 'conn' in locals() and conn:
            db_pool.putconn(conn)
        raise HTTPException(status_code=500, detail=f"Database execution error: {str(e)}")
    except Exception as e:
        print(f"General error: {e}")
        raise HTTPException(status_code=500, detail=f"Internal server error: {str(e)}")

@app.get("/health")
async def health_check():
    # Check if DB pool is initialized and can get a connection
    try:
        if db_pool is None:
            raise ValueError("DB pool not initialized")
        conn = db_pool.getconn()
        cur = conn.cursor()
        cur.execute("SELECT 1")
        cur.close()
        db_pool.putconn(conn)
        return {"status": "healthy", "database_connection": "ok"}
    except Exception as e:
        raise HTTPException(status_code=500, detail=f"Healthcheck failed: {e}")
.env File (for local development, ensure these are set in CI/CD or Docker Swarm secrets in production)
POSTGRES_DB=mydb
POSTGRES_USER=myuser
POSTGRES_PASSWORD=mypassword
Deployment Steps:
- Prepare your environment: Ensure Docker and Docker Swarm are installed and initialized on your VPS. Create the
traefik_acme.jsonfile (empty) and place it next to yourdocker-compose.yml. - Model Artifact: Place your
nemotron-3-nano-4b.gguf(or equivalent) file in a./model/directory relative to yourDockerfile.qpo. For production, theDockerfile.qpowould ideally download this from an artifact store or the volume mount would handle it. - Build QPO image:
docker build -f Dockerfile.qpo -t qpo-service:latest . - Deploy the stack:
docker stack deploy -c docker-compose.yml query_optimizer_stack
- DNS Configuration: Point
qpo.your-domain.com(andyour-domain.comfor Traefik dashboard if enabled) to the IP address of your Swarm manager node(s). Traefik will automatically provision SSL certificates.
This setup provides a highly available, cost-effective, and performance-tuned environment for your AI-augmented query optimizer, built on robust, open-source tooling.
5. Benchmark Comparison Matrix: Query Optimization Approaches
This matrix compares the key attributes of different strategies for enhancing Postgres query performance, with a focus on integrating a 4B parameter AI model.
| Feature / Approach | Traditional Postgres Planner | Cloud-Native LLM Inference (EKS/SageMaker) | Self-Hosted LLM Inference (Docker Swarm on VPS) | Application-Level Heuristics (Custom Code) |
|---|---|---|---|---|
| Latency/Throughput | Baseline (variable) | Low latency (fast inference), High throughput | Very Low latency (dedicated resources), High throughput | Moderate latency (CPU bound), Moderate throughput |
| Memory/CPU Footprint | Low (built-in) | High (EKS control plane, NATs, ALB, then inference instances) | Moderate (QPO service, model, Postgres) | Low (simple rules engines) |
| Operational Overhead | Low (DBA for tuning) | Very High (K8s complexity, managed service config) | Moderate (Docker Swarm is simpler than K8s, VM maintenance) | High (custom code to maintain, no generalizability) |
| Setup Time | Instant | Weeks (K8s cluster setup, SageMaker configs) | Days (VM provisioning, Docker setup, QPO deployment) | Days to Weeks (rules definition, integration) |
| Monthly Base Cost (before compute) | $0 | $300-$500 (EKS Tax) (control plane, NATs, ALB) | $0 (Orchestration cost is effectively zero) | $0 |
| Compute Cost (per 4B model instance) | N/A | $300-$1000+ (e.g., c6.large, ml.m5.xlarge) | $45-$60 (Hetzner AX/CX series VPS) | Minimal (part of existing app server) |
| Total Effective Cost (Base + 1x Compute) | $0 | $600-$1500+ | $45-$60 | Minimal (included in app server cost) |
| Scaling Limits | Limited by DB capacity | High horizontal scalability (complex to manage costs) | High horizontal scalability (add Swarm nodes) | Limited by app server capacity |
| Performance Gain (vs. Baseline) | 0% (baseline) | Potentially 81% faster (model dependent) | Potentially 81% faster (model dependent) | 5-20% (rule complexity dependent) |
| Complexity | Low | Very High | Moderate | Moderate |
Analysis:
- Traditional Postgres Planner: The default, simplest, but offers no AI-driven improvements.
- Cloud-Native LLM Inference: Provides the potential performance gain but comes with an astronomical base cost ("Kubernetes Tax") and high per-instance charges, making it economically unsustainable for many high-volume workloads. The complexity of managed K8s for LLM inference adds significant operational burden.
- Self-Hosted LLM Inference (Our Recommendation): Delivers the full performance benefits of a 4B model at a fraction of the cost. Docker Swarm provides robust orchestration without the Kubernetes overhead, and dedicated VPS hardware offers superior performance-to-cost ratio. This is the sweet spot for combining advanced AI with responsible infrastructure spending.
- Application-Level Heuristics: A simpler, cheaper alternative, but lacks the dynamic learning and generalized intelligence of an AI model, resulting in significantly lower performance gains and higher maintenance for custom rules.
The clear winner for achieving groundbreaking performance increases with a 4B model in a fiscally responsible manner is the self-hosted, Docker Swarm-based architecture on dedicated VPS hardware.
6. Production Trade-Offs & Edge Cases
While implementing an AI-augmented query optimizer offers significant advantages, it's crucial to understand the trade-offs and potential pitfalls.
When to Use This Approach:
- High-Volume, Complex Queries: If your application frequently executes intricate queries, especially those involving multiple joins, subqueries, or large analytical operations where Postgres's native planner often falters.
- Significant Performance Bottlenecks in Database: When
EXPLAIN ANALYZEconsistently reveals inefficient plans that lead to slow response times or high resource utilization on your Postgres server. - Cost Optimization is a Priority: When facing the escalating costs of cloud-managed services for AI/ML inference or general compute, and a shift towards more controlled, self-hosted infrastructure is strategic.
- Engineering Team with Infrastructure Competency: Your team possesses strong Docker, Linux, and network administration skills, comfortable managing a small, robust Swarm cluster.
- Data-Driven Decision Making: You have robust monitoring and observability in place to validate the AI model's effectiveness and quickly identify any performance regressions.
When NOT to Use This Approach:
- Simple CRUD Applications / Low Query Volume: For applications dominated by basic create, read, update, delete operations or those with low traffic, the overhead of an additional QPO service and model inference might not justify the complexity. The performance gains would be minimal.
- Early-Stage Startups with Limited Resources: If your team is small and focused solely on product development with limited infrastructure expertise, the initial setup and ongoing maintenance of a self-hosted QPO might divert critical resources from core product.
- Strict Real-time Latency Requirements (<1ms): While highly optimized, the inference step, even for a 4B model, introduces a measurable latency. For applications requiring sub-millisecond query execution, adding an AI layer might be counterproductive without significant hardware investment (e.g., dedicated high-end GPUs).
- Lack of Training Data or Expertise: If you don't have historical query logs, optimal plan data, or the internal ML engineering expertise to train and fine-tune a specialized 4B model, implementing this approach from scratch will be challenging.
Scaling Limits:
- QPO Service Scaling: The QPO service itself can be scaled horizontally by adding more replicas in Docker Swarm across multiple nodes. Traefik automatically handles load balancing across these replicas.
- Postgres Scaling: Postgres scaling remains a separate concern. While the QPO optimizes queries, it doesn't change Postgres's fundamental scaling limits. For read-heavy workloads, read replicas are common. For write-heavy, sharding or advanced clustering might be needed. The QPO can interact with a multi-node Postgres setup, but the complexity shifts to managing Postgres HA.
- Model Size and Latency: While 4B models are efficient, larger, more complex models for different tasks might demand dedicated GPU resources, potentially impacting the cost-effectiveness of this self-hosted approach. It's a sweet spot for the 4B class.
Failure Modes:
- QPO Service Failure: If the QPO service becomes unhealthy, applications will lose their ability to execute queries. Robust healthchecks (
docker-compose.ymlincludes one) and a fallback mechanism (e.g., direct Postgres connection if QPO is unavailable, or a circuit breaker pattern) are essential. - Model Drift: Over time, if the underlying data distribution in Postgres changes significantly, the trained 4B model might start generating suboptimal plans. Regular retraining or fine-tuning with fresh data, coupled with continuous A/B testing of model versions, is critical.
- Invalid Plan Generation: The AI model might occasionally generate an invalid or even detrimental query plan. The QPO service must validate the generated plan (e.g., by checking
EXPLAINoutput for errors) before execution and have a fallback to the original query. - Resource Contention: While resource limits are set, misconfiguration or unexpected spikes could lead to the QPO service or Postgres starving other services on a shared VPS. Careful monitoring of CPU, RAM, and I/O is non-negotiable.
This approach provides immense power, but with that power comes the responsibility of thorough engineering and proactive monitoring.
7. Strategic Decision Checklist & Consulting CTA
For CTOs, Tech Leads, and Senior Engineers, adopting an AI-augmented query optimization strategy with a 4B model requires a strategic evaluation.
Strategic Decision Checklist:
- Current Performance Bottleneck Assessment:
- Quantify: Do you have clear, quantifiable evidence (e.g., slow query logs,
EXPLAIN ANALYZEoutputs, APM data) showing Postgres query performance as a significant bottleneck in your application? - Impact: What is the business impact of these slow queries (e.g., user churn, increased cloud spend, engineering time spent on manual tuning)?
- Baseline: Establish a robust baseline for your critical query latencies and throughput before considering any AI solution.
- Quantify: Do you have clear, quantifiable evidence (e.g., slow query logs,
- Internal Capability & Resource Evaluation:
- ML Expertise: Does your team have the expertise to train, fine-tune, and maintain a 4B parameter model for query optimization, including data curation and artifact management?
- Infrastructure Expertise: Is your team proficient in Linux systems administration, Docker, and Docker Swarm to confidently set up and manage a self-hosted, production-grade infrastructure?
- Budget & Time: Are you prepared for the initial (potentially significant) investment in model training and the ongoing commitment to infrastructure maintenance, offset by long-term operational savings?
- Total Cost of Ownership (TCO) Calculation:
- Cloud vs. Self-Hosted: Perform a detailed TCO comparison between deploying your 4B model inference in a managed cloud Kubernetes environment (e.g., EKS) versus a self-hosted Docker Swarm on dedicated VPS/bare-metal. Include compute, networking, storage, and the hidden "Kubernetes Tax."
- Engineering Time: Factor in the cost of engineering hours required for initial setup, integration, and ongoing maintenance for both approaches. Do not underestimate the cost of complexity.
- Opportunity Cost: Consider the opportunity cost of not optimizing your database performance, leading to potentially higher cloud bills for larger instances, slower user experiences, and developer frustration.
By meticulously addressing these points, you can make an informed decision on whether this advanced, cost-efficient AI optimization paradigm is the right strategic move for your organization.
Unlock Peak Performance and Cost Efficiency with ScoRpii Tech
Is your Postgres database struggling under the weight of complex queries? Are your cloud bills spiraling out of control with "managed" services that offer convenience at an exorbitant price?
At ScoRpii Tech, we are battle-tested architects and engineers who build production systems that simply work—fast, reliably, and without the cloud-vendor tax. We specialize in cutting through the hype to deliver real, tangible results, just like the 81% query plan acceleration discussed in this guide.
Don't just build, engineer for dominance.
We offer unparalleled expertise in:
- Cloud Cost Optimization & De-Clouding Audits: Identify hidden expenses and design strategies to migrate from costly cloud-native setups to lean, performant, and cost-effective self-hosted solutions.
- AI/ML Production Architecture: Architect and deploy intelligent services, like our 4B query plan optimizer, that deliver significant performance gains without compromise.
- Custom Infrastructure Builds: From Docker Swarm to advanced bare-metal configurations, we build resilient, high-throughput systems tailored to your exact needs, bypassing unnecessary complexity.
Ready to transform your infrastructure from a liability into a competitive advantage?
Consult ScoRpii Tech today. Let's audit your current setup, strategize your migration, and build a future-proof architecture that prioritizes performance, cost-efficiency, and operational control.
Visit scorpiitech.com/#contact or email us at contact@scorpiitech.com to schedule your initial consultation.
What did you think?
Related Articles
Stay Updated
Get the latest tech news delivered to your reader.